-fllc-allocate
Description
By analyzing main execution paths in programs, memory multiplexing analysis is performed on loops on the main path, top hot data is calculated and sorted, and prefetch instructions are inserted to pre-allocate data to last level caches (LLCs), reducing LLC misses.
Usage
Use the -fllc-allocate option to enable the LLC feature. The -O2 or higher optimization level is required.
The following lists other related interfaces.
Option |
Default Value |
Description |
|---|---|---|
-param=mem-access-ratio=[0,100] |
20 |
Ratio of the number of memory accesses in a loop to the number of instructions. |
-param=mem-access-num=unsigned |
3 |
Number of memory accesses in a loop. |
-param=outer-loop-nums=[1,10] |
1 |
Maximum number of outer loop layers that can be unrolled. |
-param=filter-kernels=[0,1] |
1 |
Specifies whether to perform path series filtering on loops. |
-param=branch-prob-threshold=[50,100] |
80 |
Probability threshold for a branch to be considered highly probable. |
-param=prefetch-offset=[1,999999] |
1024 |
Prefetch offset distance. Generally, the value is a power of 2. |
-param=issue-topn=unsigned |
1 |
Number of prefetch instructions. |
-param=force-issue=[0,1] |
0 |
Specifies whether to perform forcible prefetch, that is, the static mode. |
-param=llc-capacity-per-core=[0,999999] |
114 |
Average LLC capacity allocated to each core in multi-branch prefetch mode. |
Result
The test case is as follows:
1 2 3 4 5 6 7 8 9 10 11 12 13 | #define N 100000 long test (long *a, long *b, long *c, int n) { long sum; for (int i = 0; i < n; i++) { c[i] = a[i] * b[i]; sum += c[i] - a[i]; } return sum; } |
Test command:
1 | gcc -O2 -fllc-allocate -S test.c -o test.s |
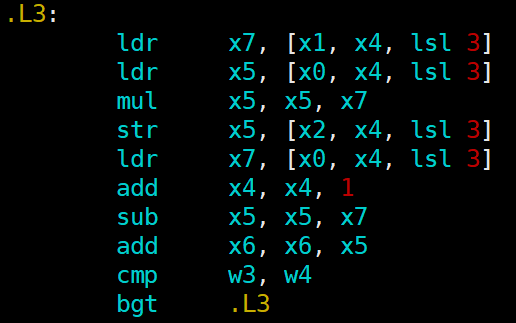
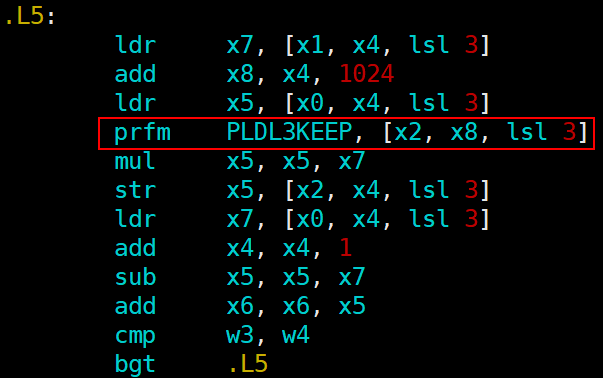
After this option is enabled, the generated assembly code adds a 1024-bit offset to the index of the data accessed by the str instruction and prefetches the data to the L3 cache (LLC of Kunpeng 920) in advance.